From Data Chaos to Business Advantage: Building an AI-Ready Data Foundation
For years, organizations have been told that data is one of their most valuable assets. In practice, many enterprises possess enormous amounts of data without being able to convert much of it into reliable business value.
Customer information exists in CRM platforms and support systems. Financial data is distributed across ERP software, spreadsheets, and accounting applications. Product behavior is recorded in analytics platforms, application databases, and logs. Operational information flows through SaaS tools and internal systems. Documents, contracts, meeting transcripts, emails, PDFs, images, and knowledge bases create an additional layer of largely unstructured information.
The problem is therefore rarely a shortage of data.
The problem is fragmentation.
As organizations adopt more cloud services, SaaS products, digital workflows, analytics platforms, and AI applications, the number of places where business information exists continues to grow. KPMG describes modern enterprise data as distributed across cloud, SaaS, and on-premises environments, stored in structured, semistructured, and unstructured formats, managed across fragmented teams, and frequently duplicated or retained longer than necessary.
This fragmentation has always complicated reporting and analytics. AI raises the stakes considerably.
An analytics dashboard based on inconsistent customer definitions may produce a misleading KPI. An AI assistant connected to inconsistent, outdated, or improperly governed information can reproduce that problem across thousands of interactions and business decisions.
Recent McKinsey research reflects the scale of this challenge. More than two-thirds of high-performing companies surveyed said data was the primary obstacle to enabling AI at scale. McKinsey argues that enterprise AI requires data that is reliable, understandable, traceable, reusable, and governed across both structured and unstructured information.
The organizations that gain an advantage from AI will therefore not necessarily be those that adopt the largest number of models or AI tools first.
They will increasingly be those that can make their own data usable.
Data Chaos Is an Architecture and Management Problem
Data chaos rarely comes from a single technical failure.
It develops gradually as organizations add systems to solve individual business problems.
Sales adopts one platform. Marketing adopts another. Finance maintains its own tools. Customer support introduces a ticketing system. Product teams build operational databases. Analytics teams create warehouses or lakes. Individual departments maintain spreadsheets and local reporting processes. Acquisitions introduce entirely new technology stacks.
Each decision may be reasonable independently.
Together, they create an environment in which the same customer, transaction, product, supplier, or business metric can exist in several systems with different identifiers, definitions, formats, and levels of freshness.
This creates a fundamental distinction between possessing data and understanding it.
An organization may technically have access to millions of records while still being unable to answer basic questions confidently: Which system contains the authoritative customer record? Who owns this dataset? When was it last updated? Which applications depend on it? Does it contain personal information? Which employees can access it? Is the information still required? Can it legally be used for a particular AI application?
These questions become increasingly important as data moves beyond dashboards and starts driving automated decisions.
Fragmentation Creates More Than an Analytics Problem
Data fragmentation is often discussed as though its primary consequence were inconvenient reporting.
The actual impact is much broader.
Different departments can calculate the same KPI differently because they use different definitions. Duplicate customer records can distort segmentation. Outdated inventory data can affect operational decisions. Inconsistent product identifiers can complicate supply chain analysis. Poorly documented transformations can make financial reports difficult to reconcile.
Fragmentation also creates cost.
Organizations store duplicate and obsolete information, operate overlapping integration pipelines, maintain redundant transformations, and spend engineering time repeatedly locating and preparing the same data.
The KPMG report highlights excessive retention as one source of higher storage costs, increased security risk, larger regulatory exposure, and additional complexity during audits and investigations.
The same problem appears from an engineering perspective. When every new application needs a custom integration with several existing systems, development teams repeatedly solve connectivity problems rather than building differentiated business capabilities.
The objective should therefore not be to connect everything to everything.
It should be to establish an architecture in which valuable data can be discovered, understood, governed, and reused.
AI Makes Data Quality More Important, Not Less
The rapid improvement of foundation models has created a tempting assumption that sufficiently capable AI can compensate for messy enterprise data.
The opposite is closer to reality.
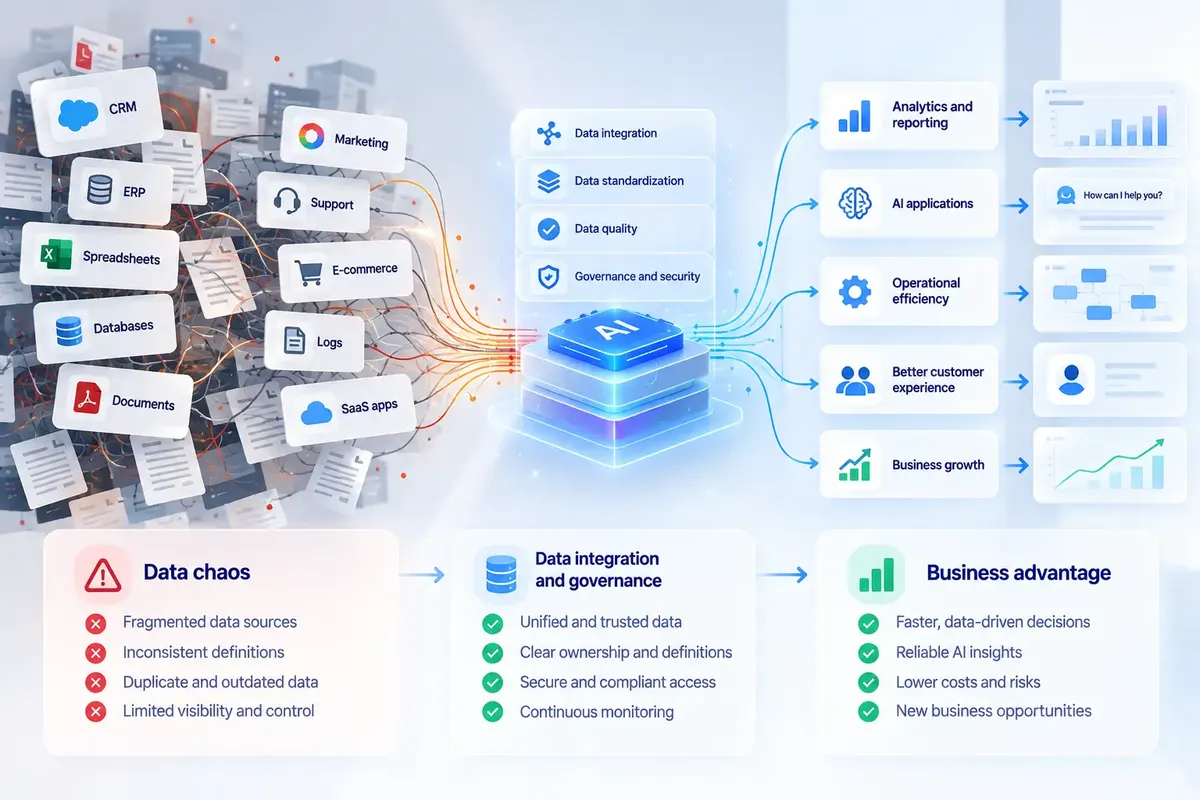
AWS describes data quality as a critical factor in realizing the potential of generative AI because the quality of training and contextual data directly affects model accuracy, bias, and reliability. Its guidance recommends identifying quality problems upstream before they reach downstream AI applications.
Traditional analytics already depends on accuracy, completeness, consistency, timeliness, and validity. Generative AI adds new dimensions to the problem.
A document may be correct but outdated.
A policy may be accurate but superseded by a newer version.
A customer record may be valid but inaccessible to the employee asking the AI assistant a question.
A document may contain the correct answer, but a retrieval system may select the wrong chunk.
An embedding index may still contain content that has already been deleted or changed in the source system.
This means AI data quality cannot stop at the original record.
McKinsey's 2026 AI data readiness research argues that quality controls now need to extend through extraction, chunking, retrieval, embeddings, indexes, and generated artifacts because an accurate source document can still produce an incorrect AI response when incomplete or obsolete fragments are retrieved.
This is one of the most important changes introduced by enterprise AI.
The organization no longer needs to govern only its source data. It increasingly needs to govern the mechanisms through which AI discovers and reconstructs that data.
Start With Visibility Before Trying to Fix Everything
Organizations cannot improve data they cannot see.
Before launching a large modernization initiative, teams need a realistic inventory of the information that already exists across the enterprise.
This includes databases and warehouses, but it should also include SaaS platforms, object storage, spreadsheets, document repositories, analytics tools, internal applications, APIs, data lakes, logs, vector databases, and other sources that may eventually participate in analytics or AI workflows.
The objective is not merely to produce a list.
A useful inventory should begin connecting technical assets to business context.
For important datasets, organizations should understand ownership, source, consumers, sensitivity, retention requirements, quality expectations, dependencies, and business purpose.
KPMG describes this transition as moving beyond the question of "what data exists" toward understanding who owns it, who accesses it, how it is used, and whether it creates business value or risk.
This context transforms a data catalog from an inventory into an operational tool.
It also prevents a common modernization mistake: spending months cleaning information that nobody actually needs.
Integrate AI into your business processes
Consult with our expertsNot All Data Deserves Equal Investment
One of the reasons enterprise data programs become overwhelming is that organizations attempt to solve the entire data estate at once.
That is rarely necessary.
A product recommendation system, financial forecasting model, customer support assistant, fraud detection service, and executive dashboard do not require exactly the same information or quality thresholds.
Data quality should therefore be connected to business use.
McKinsey makes a similar point in its current AI readiness guidance: organizations do not need perfect data before beginning AI initiatives. Instead, they should determine what "good enough" means for each use case according to its business requirements and risk profile.
This allows organizations to prioritize.
A dataset used to calculate regulatory reporting may require extremely strict lineage and validation. A dataset used to generate internal brainstorming suggestions may tolerate greater uncertainty. Customer PII requires different controls from public product documentation.
The relevant question is not whether every dataset is perfect.
It is whether the data is sufficiently reliable, current, governed, and secure for the decision or system that depends on it.
Standardization Creates a Shared Business Language
Technical integration alone does not solve data fragmentation.
Two systems can be perfectly connected and still disagree about what their information means.
One department may define an "active customer" as someone who made a purchase during the last 30 days. Another may use 90 days. Finance may count a transaction when payment settles, while product analytics counts it when checkout completes.
If these definitions remain inconsistent, moving all records into the same warehouse simply centralizes disagreement.
Organizations therefore need common definitions for important business entities and metrics.
Customer, account, product, order, revenue, churn, active user, conversion, subscription, supplier, and other core concepts should have explicit definitions and ownership.
This semantic layer is particularly important for AI.
An AI assistant can retrieve information from several systems, but if those systems use conflicting business definitions, the model has no reliable way to determine which interpretation the organization considers authoritative.
Data standardization therefore becomes part of AI readiness rather than merely an analytics concern.
Integration Should Create Reusable Data, Not Another Layer of Complexity
Once important sources and definitions are understood, organizations need a practical strategy for connecting them.
There is no single architecture appropriate for every enterprise.
Depending on the workload, teams may use ETL or ELT pipelines, event streaming, APIs, change data capture, data virtualization, lakehouse architectures, data warehouses, operational data stores, or combinations of these approaches.
The architectural objective matters more than the label.
Data should move between systems in a predictable way, transformations should be observable, ownership should remain clear, and new consumers should be able to reuse existing data products rather than constructing another isolated integration.
AWS's current generative AI architecture guidance identifies scalability, storage and retrieval efficiency, security, privacy, data quality, versioning, lineage, and cost-effective management as core considerations for AI-oriented data architectures.
That combination is important.
A technically sophisticated data platform that nobody can understand or govern simply creates a more expensive form of data chaos.
Build, Buy, or Bridge?
Data modernization also raises a familiar architectural question: which capabilities should be built internally and which should be purchased?
Building everything provides control but creates substantial engineering and maintenance responsibilities.
Buying everything can accelerate implementation but may introduce vendor dependence, integration constraints, or functionality that does not match the organization's processes.
For many enterprises, the most practical answer lies between those extremes.
Commodity capabilities such as connectors, storage engines, orchestration, cataloging, monitoring, or standard transformation infrastructure often provide little competitive advantage when rebuilt internally. Existing platforms can solve these problems faster and allow engineering teams to focus on capabilities that are specific to the business.
Custom engineering becomes more valuable where the organization's processes, domain knowledge, data relationships, customer experience, or analytical models genuinely differentiate the company.
This creates a useful third strategy: bridge.
An organization can use an existing platform to solve an immediate integration problem while designing its longer-term architecture so that individual components remain replaceable. This reduces time to value without forcing every temporary decision to become permanent infrastructure.
The important architectural property is therefore not complete independence from vendors.
It is controlled replaceability.
Not sure how to proceed with AI integrations?
We are ready to helpGovernance Should Be Built Into the Data Flow
Governance often fails because it is treated as documentation surrounding the data platform rather than functionality inside it.
Policies may specify who should access sensitive information, how long records should be retained, or which information may be used for AI. If those policies are enforced manually, however, they become difficult to maintain as the organization scales.
Modern governance needs to travel with the data.
Classification, ownership, access permissions, lineage, retention policies, quality status, and sensitivity metadata should become part of the operational data environment wherever possible.
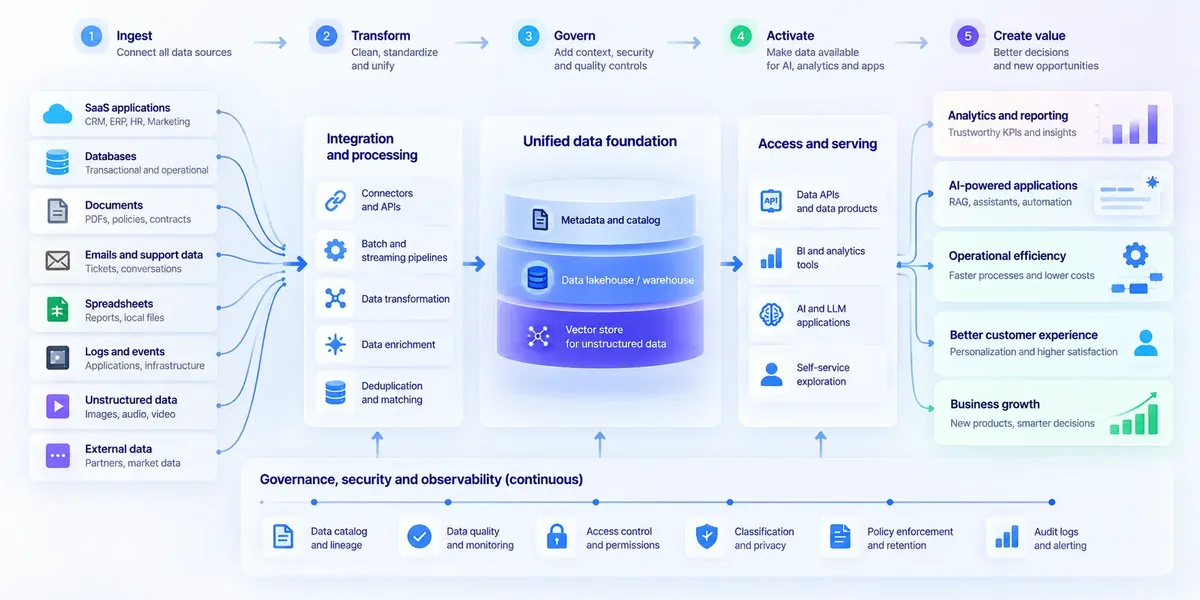
AWS notes that generative AI increases the importance of governance because enterprise AI frequently combines structured warehouse data with unstructured documents, transcripts, images, and other knowledge sources that historically may not have received the same governance treatment.
The access problem also changes.
A document may be protected correctly in its original repository while portions of its contents have already been extracted, embedded, and placed into a vector index used by an AI assistant.
Security controls therefore need to follow information through transformation.
Data Lineage Becomes Essential for Trust
When an executive sees a surprising number in a dashboard, one of the first questions is usually where it came from.
AI creates the same requirement at greater complexity.
A generated answer may combine information from several documents, retrieved fragments, database records, transformations, and model reasoning. If the organization cannot identify which sources influenced the answer, investigating errors becomes difficult.
Lineage provides that connection.
Traditional lineage tracks how data moves from source systems through transformations into reports and downstream applications. AI-ready lineage increasingly needs to include extracted content, chunks, embeddings, indexes, retrieval processes, prompts, and generated artifacts.
This does not mean every AI interaction needs an enormous forensic record.
It means critical AI systems should provide enough traceability to answer practical questions about the origin, version, transformation, and authorization of the information used.
Without that capability, trust becomes difficult to scale.
Data Security and Privacy Cannot Be Separated From Data Strategy
Centralizing or connecting data creates value, but it can also increase exposure.
A fragmented organization may accidentally have weak security because nobody understands where sensitive information resides. A highly integrated organization can create a different problem if excessive numbers of systems and employees gain access to a consolidated data layer.
The objective is therefore controlled accessibility.
Sensitive information should be discoverable by governance systems without automatically becoming accessible to every application.
Classification, encryption, identity management, role-based or attribute-based access controls, masking, retention policies, auditability, and data minimization all become part of the data architecture.
This is especially important when AI systems participate because natural-language interfaces can make enterprise information substantially easier to query.
A user who would never manually inspect thousands of records may be able to ask an AI system to summarize them instantly.
The authorization layer must therefore determine not simply what the AI can technically retrieve, but what the specific user is permitted to know.
NIST is currently developing a Data Governance and Management Profile that connects data governance priorities with privacy and cybersecurity risk management, with mapping to the AI Risk Management Framework planned as the profile evolves.
Excess Data Can Be a Liability Rather Than an Asset
The phrase "data is the new oil" encouraged organizations to collect information aggressively.
That mindset deserves reconsideration.
Data that has no current or plausible business purpose still consumes storage, increases backup volumes, expands the attack surface, complicates discovery, and creates potential privacy and regulatory obligations.
KPMG's framework explicitly includes data deletion and reduction as part of reducing enterprise data risk.
This suggests that a mature data strategy should ask two questions rather than one.
The first is: what information should we make more usable?
The second is: what information should we stop keeping?
Reducing redundant, obsolete, and trivial data can sometimes create business value faster than building another analytics capability because it simultaneously lowers complexity, cost, and risk.
AI Readiness Requires Structured and Unstructured Data
Traditional enterprise data programs concentrated heavily on structured information.
AI changes that balance.
Contracts, PDFs, presentations, product documentation, support tickets, emails, transcripts, images, policies, meeting notes, knowledge bases, and other unstructured content increasingly become inputs to AI systems.
AWS notes that generative AI architectures must govern both structured and unstructured enterprise knowledge and extend privacy and access controls into the data pipelines and retrieval processes used by LLM applications.
This means AI readiness cannot be measured only by the quality of the data warehouse.
Organizations also need to understand whether important unstructured information can be discovered, classified, updated, secured, retrieved, and traced.
A perfectly governed customer table does not compensate for a knowledge assistant retrieving a five-year-old policy document from an unmanaged file share.
RAG Does Not Fix Bad Data
Retrieval-Augmented Generation is often introduced as a way to connect foundation models to enterprise knowledge without retraining the model.
That is correct, but it can create the impression that connecting a vector database to company documents automatically solves the enterprise knowledge problem.
It does not.
RAG can retrieve stale information, irrelevant chunks, duplicate documents, conflicting versions, incorrectly classified content, or information the requesting user should not be allowed to access.
Retrieval quality therefore depends on the data architecture around it.
Documents need lifecycle management. Metadata needs to describe context. Access controls need to survive ingestion and indexing. Updates need to propagate. Deleted content needs to disappear from downstream indexes. Retrieval needs evaluation. Sources should be traceable where the use case requires it.
AWS's Well-Architected guidance for generative AI similarly emphasizes efficient indexing, current information, privacy, security, quality, versioning, and lineage in RAG-oriented architectures.
The vector database is therefore one component of AI infrastructure.
It is not a substitute for data management.
Data Observability Turns Governance Into a Continuous Process
A one-time cleanup project cannot permanently solve data quality.
Sources change. Schemas evolve. APIs fail. New applications appear. Business definitions change. Documents become outdated. Pipelines break. Ownership moves between teams.
Organizations therefore need continuous visibility into the health of important data flows.
Data observability extends traditional infrastructure monitoring into questions such as whether expected records arrived, whether schemas changed, whether freshness deteriorated, whether volumes suddenly shifted, whether a transformation failed, and whether downstream consumers are receiving reliable information.
AI adds another layer.
McKinsey argues that observability for AI should extend beyond ingestion and transformation into retrieval behavior, context assembly, content freshness, citation integrity, and generated outputs.
This makes data quality an operational capability rather than a periodic project.
Ownership Is as Important as Technology
Many data problems persist because everybody uses the data but nobody owns its quality.
A governance document cannot fix that ambiguity.
Important data domains need accountable owners or stewards who understand both their technical characteristics and business meaning.
AWS recommends assigning data quality stewards to major domains so that standards, automated checks, and ongoing monitoring have clear responsibility rather than belonging vaguely to "IT."
This also improves collaboration between business and engineering teams.
Business stakeholders understand what information means and which errors matter. Data engineers understand how it moves and transforms. Security and privacy teams understand exposure. AI teams understand how models consume it.
Data governance works when those perspectives become part of the same operating model.
It fails when governance becomes a separate administrative function disconnected from the systems and decisions it is supposed to govern.
Start With a Business Outcome, Not a Platform
Large data transformation programs often begin with a technology decision.
The organization decides that it needs a new warehouse, lakehouse, catalog, integration platform, governance suite, or AI stack and then searches for problems the platform can solve.
A more reliable sequence begins with a business outcome.
Perhaps customer support needs a trustworthy AI assistant.
Perhaps finance needs faster consolidated reporting.
Perhaps operations needs real-time inventory visibility.
Perhaps sales needs a unified customer view.
Perhaps the company needs to reduce the amount of sensitive data stored across uncontrolled systems.
Once the outcome is defined, teams can identify the data required to achieve it, evaluate its current quality and accessibility, resolve the most important gaps, and build only the architecture necessary to support that outcome.
AWS recommends a similar approach for generative AI adoption, combining explicit business success criteria with a minimum viable governance framework and early integration of structured and unstructured data.
This produces measurable progress sooner and reduces the risk of a multi-year transformation program that creates infrastructure without creating business value.
Quick Wins Should Become Reusable Foundations
Starting small does not mean building disposable prototypes.
The strongest early data initiatives solve a narrow problem while establishing components that can be reused later.
A customer support AI project might require a document ingestion pipeline, access-aware retrieval, metadata standards, data freshness controls, and evaluation processes.
Those capabilities can later support sales enablement, employee knowledge search, onboarding, or compliance workflows.
A customer analytics project may establish canonical customer identifiers, integration patterns, quality checks, and ownership rules that later support personalization or churn prediction.
This is how incremental implementation becomes strategic.
Each project creates immediate value while strengthening the organization's underlying data capability.
Build Your AI-Ready Data Foundation
Start with a callFrom Data Visibility to Data Intelligence
Knowing where information exists is necessary, but it is not the final objective.
The more mature capability is continuous data intelligence.
KPMG describes this as moving beyond point-in-time discovery toward continuously understanding which data matters, reducing unnecessary information, prioritizing risk, and taking action that produces measurable business outcomes.
That transition changes how organizations think about data.
A catalog tells the organization that a dataset exists.
Data intelligence helps determine what it means, who owns it, whether it is trustworthy, how it is being used, what depends on it, whether it creates risk, and what action should be taken.
The difference is similar to the difference between inventory and operations.
One describes the environment, the other continuously manages it.
The Real Business Value Appears After the Foundation Exists
Good data architecture is not valuable because the organization owns cleaner tables.
Its value appears in what the business can do differently.
Reliable integrated information can shorten reporting cycles because teams spend less time reconciling contradictory numbers. Better customer data can improve segmentation and personalization. Trusted operational data can improve forecasting and resource allocation. Clear ownership and lineage can reduce the time required to investigate incidents or respond to audits.
AI expands those opportunities further.
A governed knowledge foundation can support enterprise search, customer service assistants, document analysis, automated classification, recommendation systems, forecasting, decision support, and agentic workflows.
AWS summarizes the outcome similarly: organizations that treat data as a strategic asset and invest in governance, quality, and security are better positioned to move generative AI from experimentation toward enterprise-scale deployment and measurable outcomes.
The advantage therefore comes from reducing the distance between information and action.
Data Readiness Should Be Measured, Not Assumed
Before launching a major analytics or AI initiative, organizations should assess whether the required data foundation actually exists.
KPMG's readiness framework groups these questions around visibility and control, risk and compliance, the operating model, and AI readiness. It asks whether organizations can connect information to ownership and usage, identify risk, respond to regulatory requests, align AI and governance teams, operate a scalable governance model, and determine whether data is sufficiently trusted for AI.
A practical assessment can apply the same logic to a specific use case:
Do we know which data the system needs?
Do we know where that information originates?
Is there an authoritative source?
Can we measure its quality and freshness?
Do we know who owns it?
Can access controls be enforced throughout the data flow?
Can we trace important outputs back to their sources?
Can changes propagate reliably to downstream systems?
Can we detect when the data becomes stale or incorrect?
Can we remove information when it should no longer be retained?
If several answers are unclear, the organization may not have an AI problem yet.
It has a data foundation problem.
A Practical Roadmap From Data Chaos to Business Value
The transition does not require organizations to rebuild their entire data estate before delivering value.
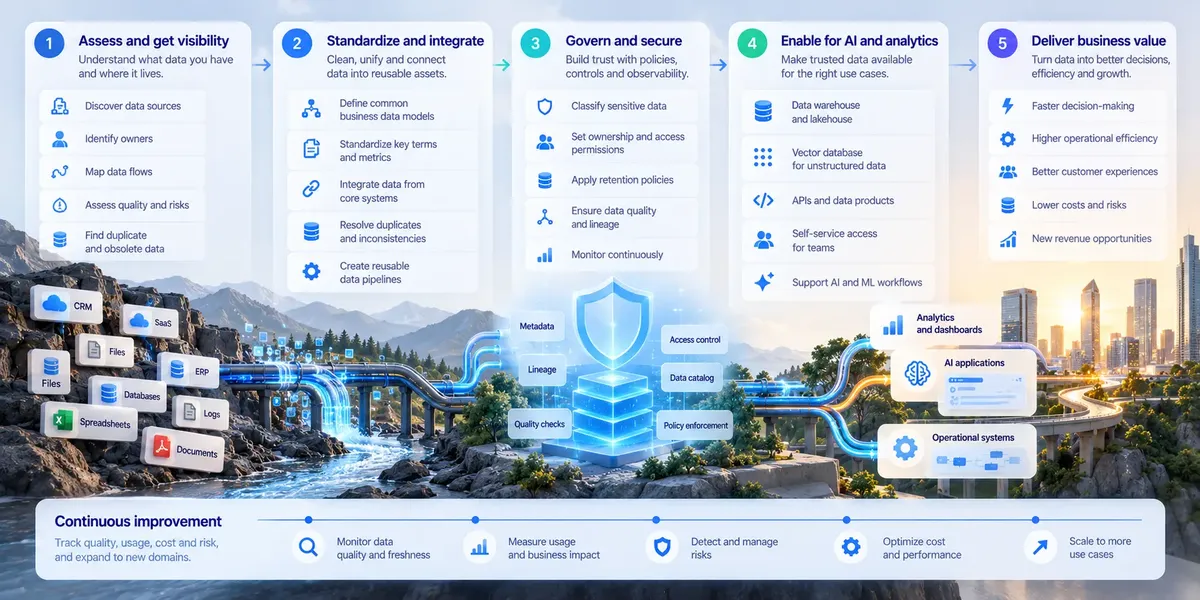
The first stage should establish visibility around a clearly defined business domain. Teams identify relevant systems, data owners, sensitive information, dependencies, quality problems, and existing integrations.
The second stage establishes shared meaning. Important entities and metrics receive agreed definitions, authoritative sources are identified, and minimum quality requirements are connected to the business use case.
The third stage improves integration. Rather than creating point-to-point connections for every new consumer, the architecture begins producing reusable and governed data products or services.
The fourth stage operationalizes governance. Classification, access controls, retention, lineage, quality checks, monitoring, and ownership become part of the data flow rather than external documentation.
The fifth stage introduces analytics or AI against that controlled foundation. The initial use case should be sufficiently valuable to demonstrate business impact while remaining narrow enough to evaluate clearly.
The final stage is continuous improvement. Teams monitor quality, usage, cost, risk, and business outcomes while extending successful patterns into additional domains.
This sequence avoids both extremes.
Organizations do not need to spend years building a theoretically perfect enterprise data platform before delivering value, but they also avoid connecting AI directly to unmanaged information and hoping the model can compensate for the underlying disorder.
Turn Data Into Business Value
Contact our expertsData Strategy Is Ultimately a Business Strategy
Data transformation frequently becomes trapped inside technical language.
Warehouses, lakehouses, pipelines, catalogs, schemas, embeddings, vector stores, lineage, and governance platforms all matter, but none of them represents the business objective.
The objective is to make reliable information available to the right people and systems at the right moment, under the right controls, so that the organization can make better decisions and build better products.
This is why the divide between "business" and "data" becomes increasingly artificial.
Pricing, customer experience, operations, risk, product development, forecasting, automation, and AI all depend on information.
An organization that cannot agree on what its data means will eventually struggle to automate decisions based on it.
An organization that cannot determine who should access information will struggle to deploy enterprise AI safely.
An organization that cannot trace data through its systems will struggle to trust increasingly automated outcomes.
The technical foundation therefore matters because the business increasingly operates through it.
Conclusion
Data chaos is not solved by collecting more data.
It is solved by making the data an organization already possesses visible, understandable, reliable, integrated, governed, secure, and useful.
That process begins with knowing what exists and why it matters. It requires shared definitions so that business units do not operate with incompatible versions of reality. It requires integration architecture that creates reusable information rather than another generation of point-to-point connections. It requires quality controls, ownership, lineage, security, retention policies, and continuous observability.
AI makes all of these disciplines more urgent.
Models can retrieve and synthesize information at a scale that traditional applications could not, but they can also amplify stale, inconsistent, improperly authorized, or poorly understood information just as efficiently.
This is why AI readiness is increasingly inseparable from data readiness.
The strongest organizations will not wait until every dataset is perfect. They will identify valuable use cases, determine what trustworthy data means for those use cases, establish the minimum architecture and governance required, deliver measurable results, and then reuse those foundations elsewhere.
Over time, the result is more than cleaner data.
It is an organization capable of turning fragmented information into reliable decisions, scalable AI systems, operational efficiency, and new sources of business value.
The goal is not to eliminate every form of data complexity.
It is to make complexity manageable enough that the business can use its information with confidence.
